The Cluster and Health sections give operators and support a read-only window into the running installation. You don't need them for day-to-day VAM use.
Cluster
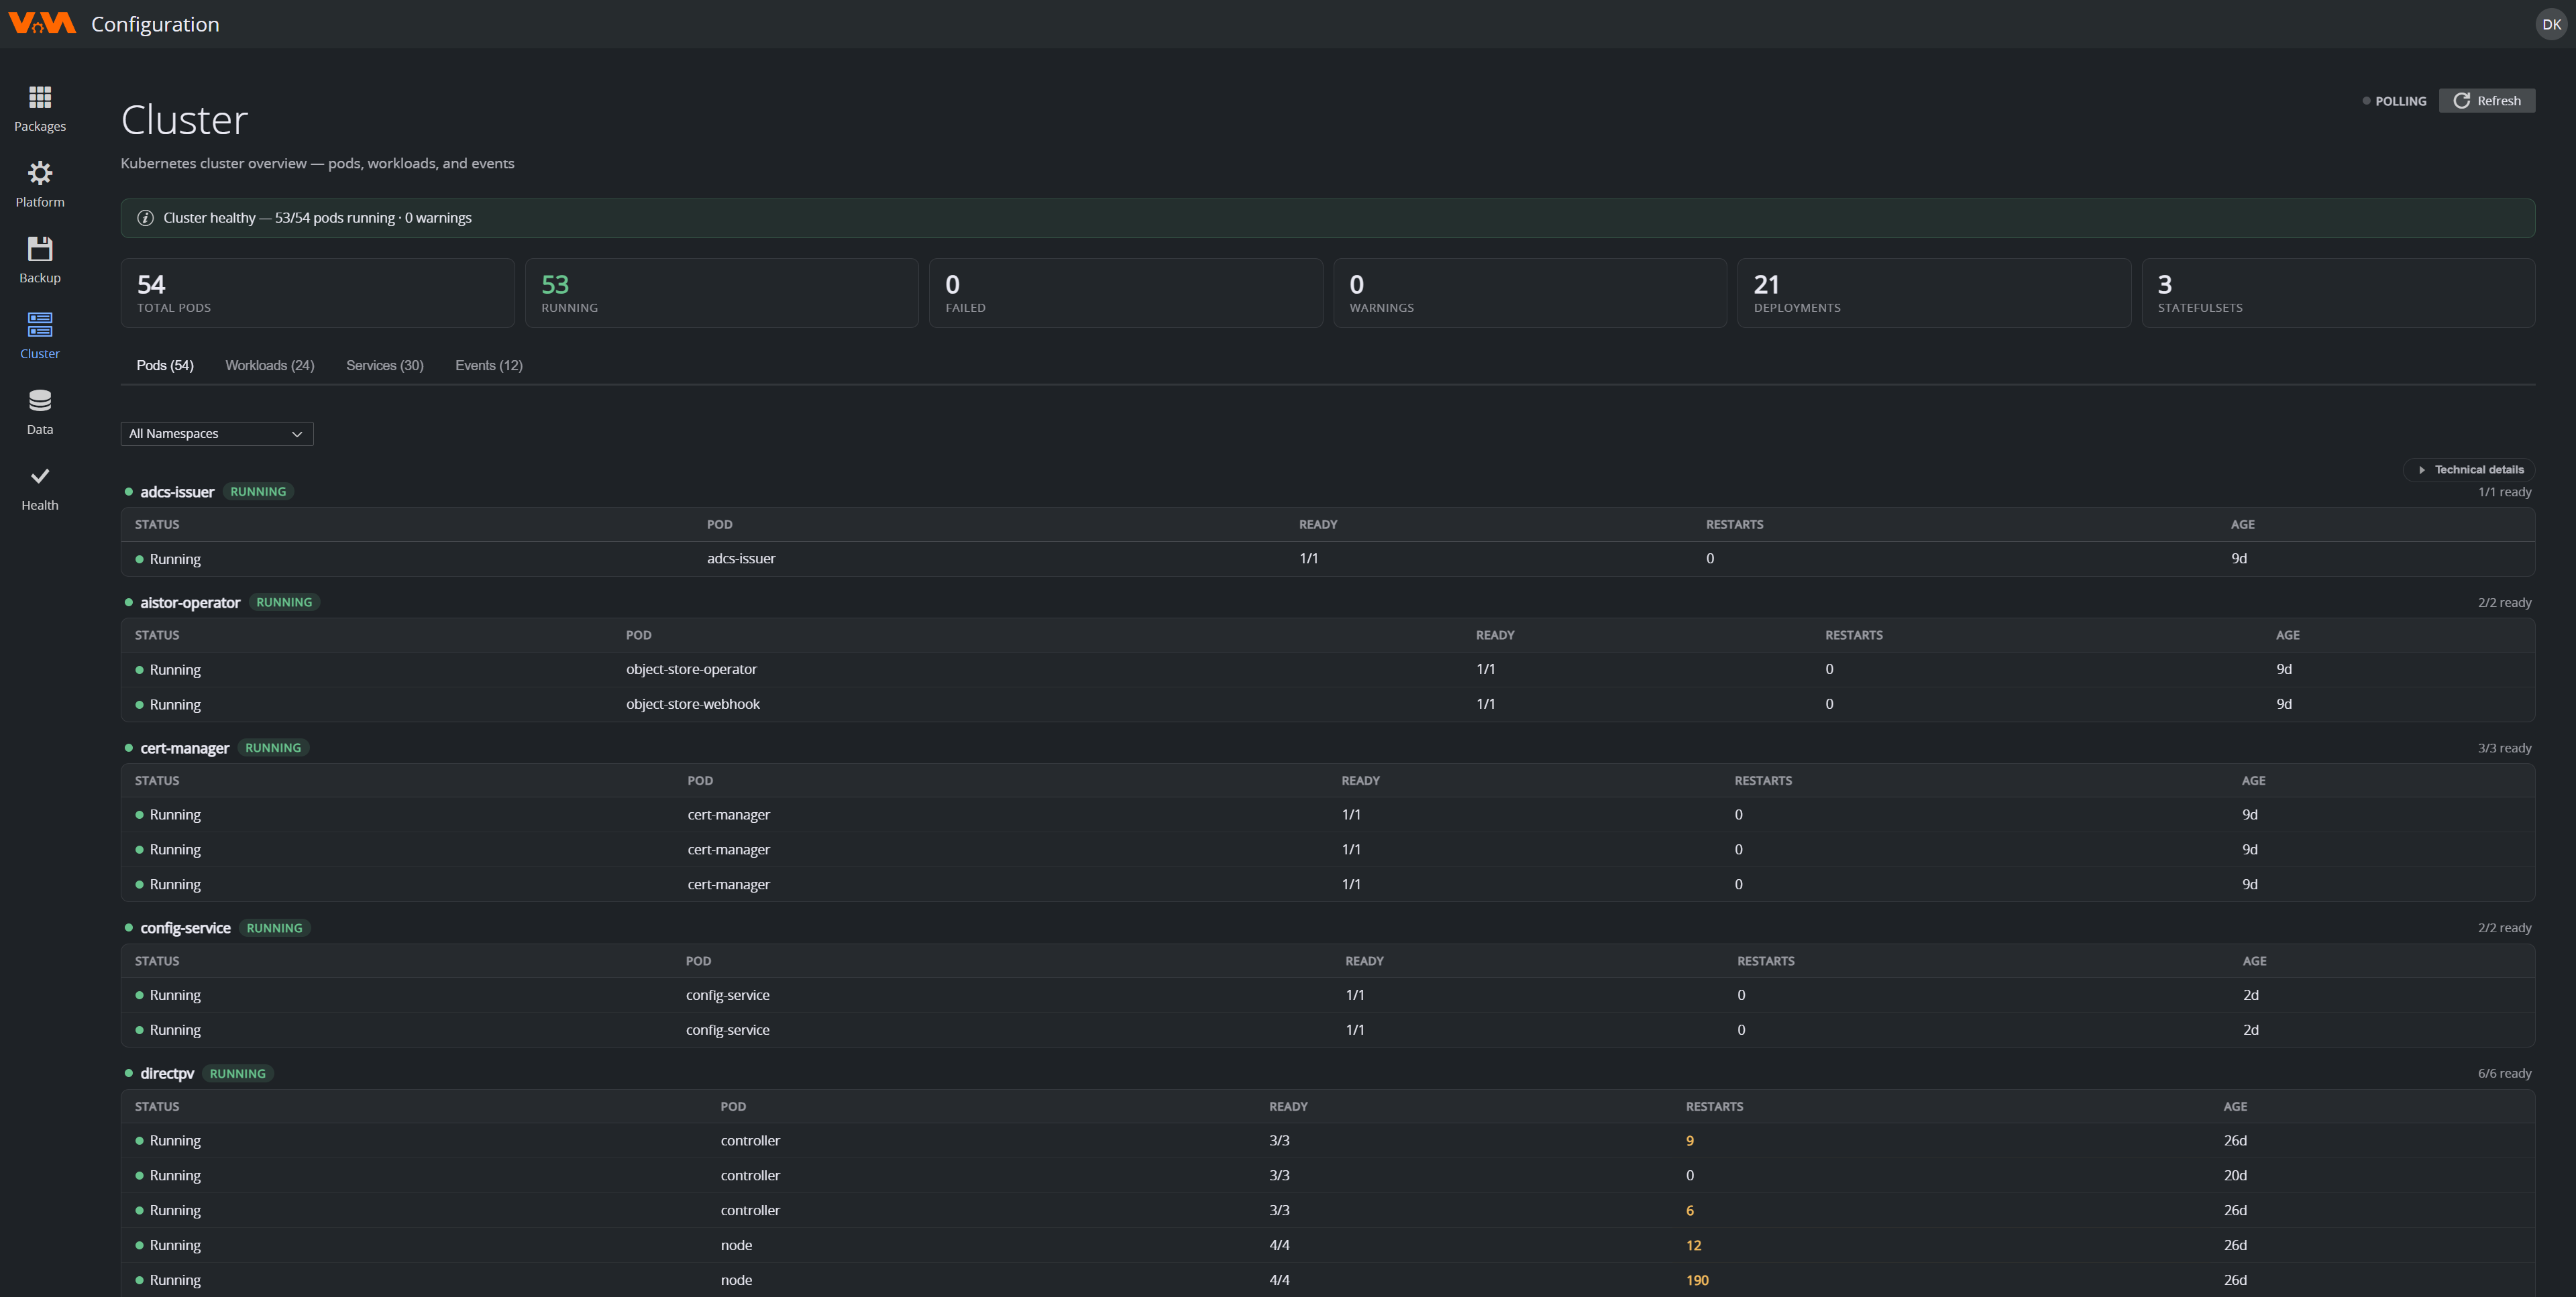
Cluster in the navigation is a live view of the Kubernetes cluster that hosts VAM. The header counts the pods and workloads in Total Pods, Running, Failed, Warnings, Deployments and StatefulSets, with an overall "Cluster healthy" banner. It refreshes automatically (live), and there's a Refresh button.
Tabs:
- Pods: every pod (filterable by namespace), grouped by package, with ready count, restart count (non-zero is a warning sign) and age. A Technical details expander shows more.
- Workloads: deployments and statefulsets, with their ready replicas against the desired count.
- Services: Kubernetes services.
- Events: recent cluster events.
Healthy looks like: all workloads green, zero pods in Failed and only a few pods in Starting for a short time during upgrades. Open a pod to see the state of its containers, for example CrashLoopBackOff or ImagePullBackOff, and use Open logs / full detail to read its log. The Logs tab of the package that owns the pod shows the same log, see Managing Packages > Reading Package Logs.
The view does not show node status. The installer shows how many nodes are ready: choose the Manage Existing Cluster workflow and select the cluster on Existing Clusters.
Health (System Health Check)
Health runs a coordinated health scan across the whole installation. It is the same kind of check the installer runs after deployment, available on demand. Click Run Checks.
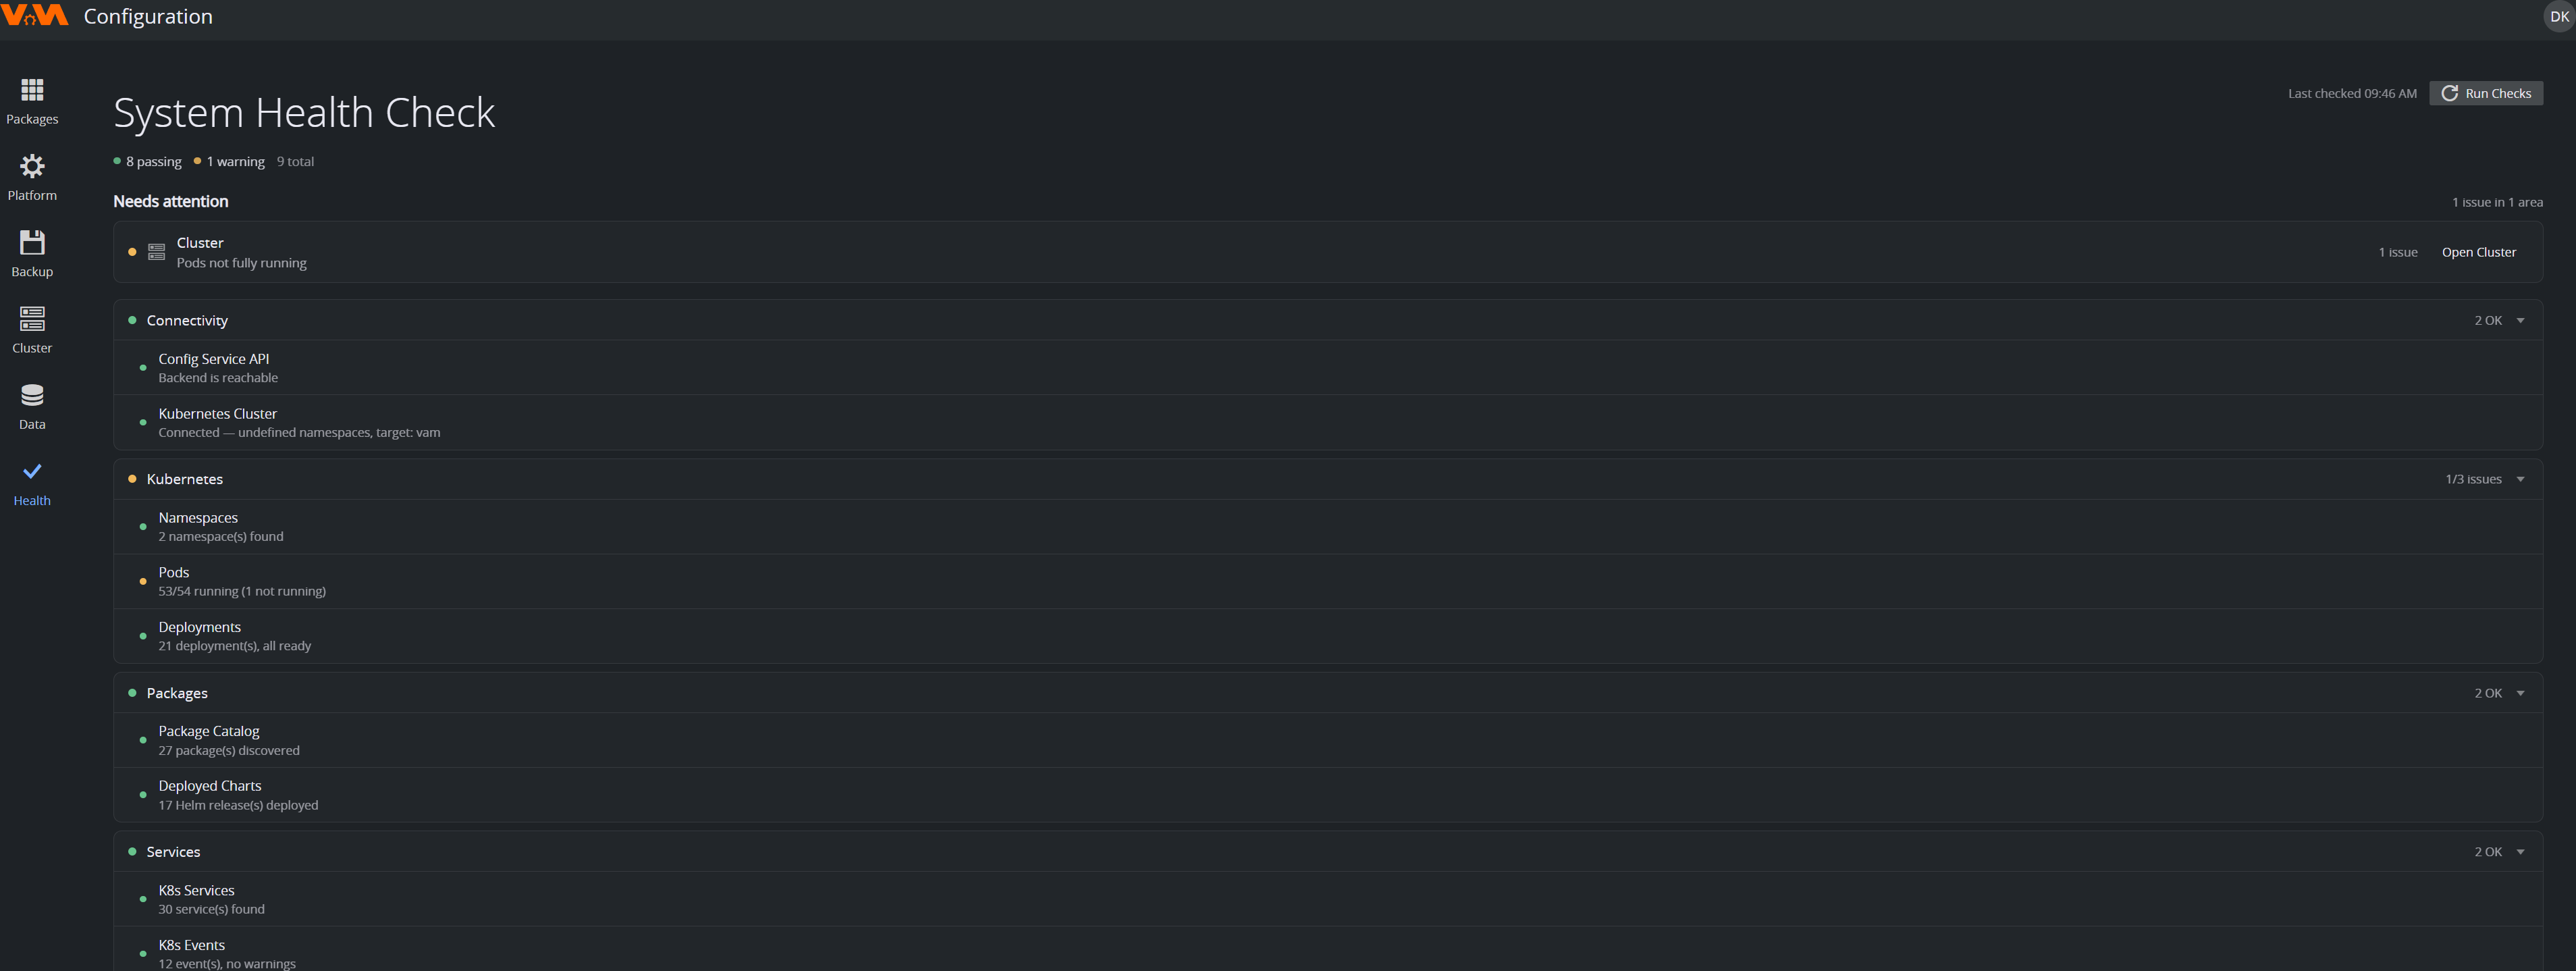
Results are grouped into areas: Connectivity, Kubernetes (namespaces, pods, deployments), Packages and Services, each shown as OK or with a count of issues, plus a Needs attention summary at the top that links straight to the relevant area (for example, Open Cluster).
Run it after any upgrade or configuration change, when a user reports an issue you can't reproduce and before opening a support case.
When to Escalate
Open a support case if any of these are true:
- A node has been Not Ready for more than ~15 minutes and a restart doesn't fix it.
- A pod is in
CrashLoopBackOffand its logs don't explain why. - Health-check failures persist after applying the suggested remediations.
- The whole Configuration Service is unreachable.